ZOOP · Creator network
Personal feeds for 10,000+ monthly users
10K+monthly users get a personal feed
Recommendations · ML · AWS
I'm Artem Zelenskii, an AI/ML engineer in Vienna. For the last 5 years I have built recommendation engines, RAG pipelines and AI agents, from the first data pipeline to live inference.
Selected Work
About
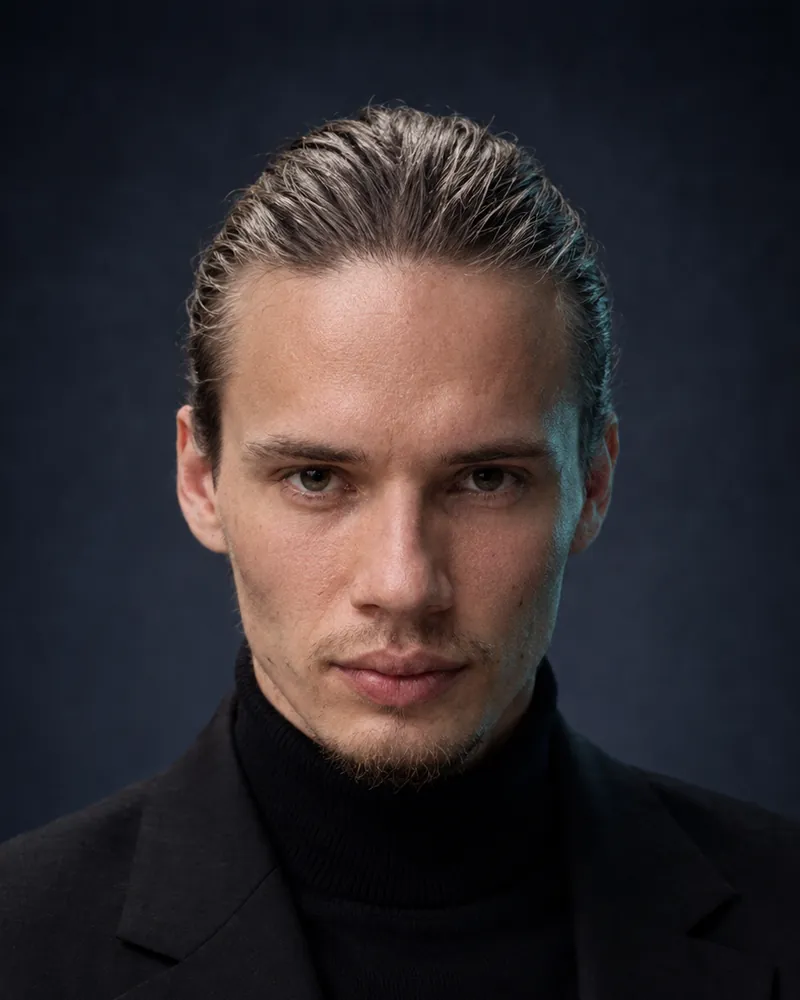
I'm Artem, an AI/ML engineer based in Vienna. I work in German, English and Russian.
For the last 5 years I have built the AI and machine learning side of applications. At ZOOP I was the data science developer and recommendation system architect. I built the recommendation engine from scratch: the signal pipeline, retrieval, ranking, cold-start rules for new users and creators, and scheduled retraining on AWS. Today 10K+ monthly active users open a feed ranked for them.
Since then I have built recommendations for a top-15 global grocer, an AI lead-scoring CRM for a B2B SaaS company, a chess tournament platform listed by the German Chess Federation, and AI agents that run content and social media routines on their own.
Every agent I build starts by assisting a person, then drafts work for a named person to approve. It acts on its own only for narrow, low-risk tasks you sign off on, with a full log of what it did.
Map the work
I sit with the people who do the work and map how it really runs today, workarounds included.
Design the guardrails
With you, I pick the processes that are ready to automate and set approval steps for each one before I build anything.
Build and prove
I build against real cases from your business and test against a held-out dataset with pass bars set in advance.
Connect and run
The system joins the tools your team already uses, with cost per run, spend caps and an alert to a person when a run fails.
Grow and hand over
I extend what the system does on its own only as the evidence supports it. You own the full code and data of your version.
What I do
Feeds and catalogs that feel personal from the first session. Retrieval, ranking, cold start and retraining.
LLMs that answer from your own data or score your leads, each decision with a written reason, tested on held-out data before launch.
Agents in n8n and Telegram that handle daily routines, from video-to-article pipelines to running 100+ Instagram accounts from one chat.
Event pipelines, Airflow ETL and model serving on AWS, built to re-run safely from stored raw data.
What I build with
The tools I reach for by default. The right stack still depends on what you are building, so I treat this as a starting point, not a template.
Recommendation and ranking models, from retrieval and cold-start rules to scheduled retraining.
Embeddings, dense and keyword search and re-ranking, as one search layer the whole system shares.
Agents with one narrow role each and their own tools. I pick the model on merit and keep it switchable.
Scheduled pipelines and retraining on AWS, packaged the same way from laptop to production.
Python APIs next to the ML layer, so logic lives in one language, and dashboards your team works in.
Queues
Every handoff between processes goes through a durable queue. If a consumer is down, the task waits instead of vanishing.
Guardrails
I scope every agent action in advance. Sending email, moving money or deleting a record sits behind an approval step by default.
Data security
Secrets live in a vault, never in the repo. Access is scoped per service, data is encrypted in transit and at rest, and sensitive actions are logged.
Let's talk
Tell me what you want to automate or personalize, and what data you already have. I'll reply with how I would approach it.